Intel Names Crescent Island the GPU D-Series for AI Inference


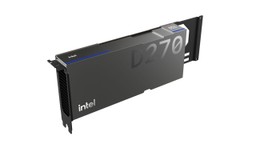
On October 13, 2026, at the Open Compute Project (OCP) Global Summit, Intel gave its “Crescent Island” accelerator a product name — the Intel GPU D-series — and published the first set of headline performance figures for a card aimed squarely at AI inference rather than training. Built on Intel’s Xe3P architecture, the D-series combines up to 480 GB of LPDDR5X memory, 1.5 TB/s of memory bandwidth and 1.3 petaflops of FP8 compute inside a 350-watt, air-cooled PCIe card. Intel says the design is meant to improve “the economics of sustained, memory-intensive AI inference.”
Intermediate

What Intel Announced
According to Intel’s newsroom post, the D-series is “designed for AI inference workloads” and targets large language models, long-context workloads and concurrent inference services. Intel states that a single card can host models with up to 300 billion parameters, and that an eight-GPU system scales past one trillion parameters — the kind of capacity that matters for serving, where growing KV caches push memory footprint faster than they push raw compute.
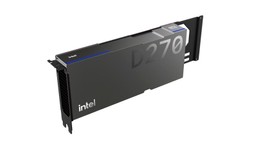
Two memory configurations are involved. Intel’s own branded card ships with 160 GB of LPDDR5X, while the company says its design “enables partners to build ODM branded cards with flexible options up to 480GB memory.” The card uses a standard PCIe form factor with air cooling, which Intel positions as a way to “scale inference without specialized rack or cooling infrastructure.” Customer sampling is underway, but Intel has not disclosed pricing or general availability.
Alongside the GPU, Intel announced Xeon-based rack designs for agentic AI, including select Xeon 6+ configurations that scale beyond 46,000 cores per rack at 133.45 kW of total rack power, and noted it has made 116 contributions to the Open Compute Project since 2011.
Inside the Xe3P Architecture
The D-series silicon is a purpose-built inference part rather than a repurposed graphics chip. Intel describes it as a 350 W accelerator with 1.5 TB/s of memory bandwidth and 1.3 petaflops of FP8 throughput. Independent coverage adds more granular detail: TechPowerUp reports the part carries 32 Xe3P cores, 256 XMX engines, 256 vector engines and 32 MB of unified L2 cache, with the XMX engines redesigned from the four-deep systolic pipeline on the standard Xe3 to a 16-deep design on Xe3P. It also reports FP4 support alongside FP8, 1 MB register files per core and 512 KB of L1 cache per core, plus a media engine with four encoders and four decoders. Notably, TechPowerUp says there are no graphics processing elements on the die — the silicon is intended only for AI inference.

The core-count, cache and XMX details were first laid out at Hot Chips in August 2026, and the framework that reaches the D-series is the same Xe software foundation Intel uses across its GPU lines — which Intel says provides application portability across its GPU platforms and support for “the AI frameworks, serving engines and development tools already used across the industry.” Intel also cites Day 0 support for Meta’s Muse Glimmer, a 30-billion-parameter open-weight model, as an example of bringing new open models up quickly.
What This Means
The D-series is a deliberate trade-off. Intel’s shipping PCIe inference accelerator, Gaudi 3, carries 128 GB of HBM2e at 3.7 TB/s of bandwidth; by comparison, StorageReview notes the D-series goes to roughly four times the memory capacity per card at well under half the bandwidth, using LPDDR5X instead of HBM partly so the card can drop into existing air-cooled racks. For decode-heavy serving, Intel is betting that capacity per watt and per dollar matters more than peak bandwidth.
“Inference is becoming the defining AI workload, and enterprises need infrastructure that delivers the right performance at the right cost,” said Anil Nanduri, vice president of AI Products and GTM at Intel’s Data Center Group. “With Intel GPU D-series, we’re focused on making high-capacity inference practical to deploy and economical to scale.”
Nicolas Dubé, corporate vice president in Intel’s Data Center Systems and Solutions Group, framed the broader push around heterogeneous compute: “Open models are expanding the options enterprises have for deploying AI. To realize their full potential, organizations need infrastructure that can match different workloads with the right intelligence, right compute resources and right economics.”
As with any pre-launch accelerator, the open questions are cost per generated token, software maturity and independent performance results, none of which have been published. TechPowerUp notes that pricing, general availability and independent performance testing have yet to be disclosed. Until those exist, the D-series is a statement of intent about where Intel believes inference economics are heading — not yet a benchmarked contender.
Related Coverage
- Intel’s Crescent Island GPU: 160GB LPDDR5x Memory Revolutionizes AI and High-Performance Computing — RITS’s earlier October 2025 look at the Crescent Island project when it was still a codename and only a 160 GB memory figure was public.
This post was drafted with AI assistance and reviewed by RITS staff.
Sources
- Intel Newsroom — “Intel Accelerates Open Infrastructure for the Agentic AI Era”
- Intel — GPU D-series product page
- TechPowerUp — “Intel ‘Crescent Island’ GPU Gets D-Series Name, Supports Up to 480 GB of LPDDR5X”
- StorageReview — “Intel GPU D-Series Packs 480GB LPDDR5X and 1.3 PFLOPS FP8 into a 350W PCIe Card”


 沪公网安备31011502017015号