AdvancedAI
Bankai: Kilobyte-Scale Patches for 1-Bit LLMs via XOR Adaptation
- AI
- llm
- open source
- quantization
Bankai is the first post-training adaptation method for true 1-bit large language models. Released on April 2, 2026, it uses bitwise XOR operations on binary weights to create kilobyte-scale patches that modify model behavior with zero inference overhead. Where LoRA adapters weigh ~100 MB each, a Bankai patch compresses to roughly 1 KB — and can be hot-swapped in microseconds.

The Problem
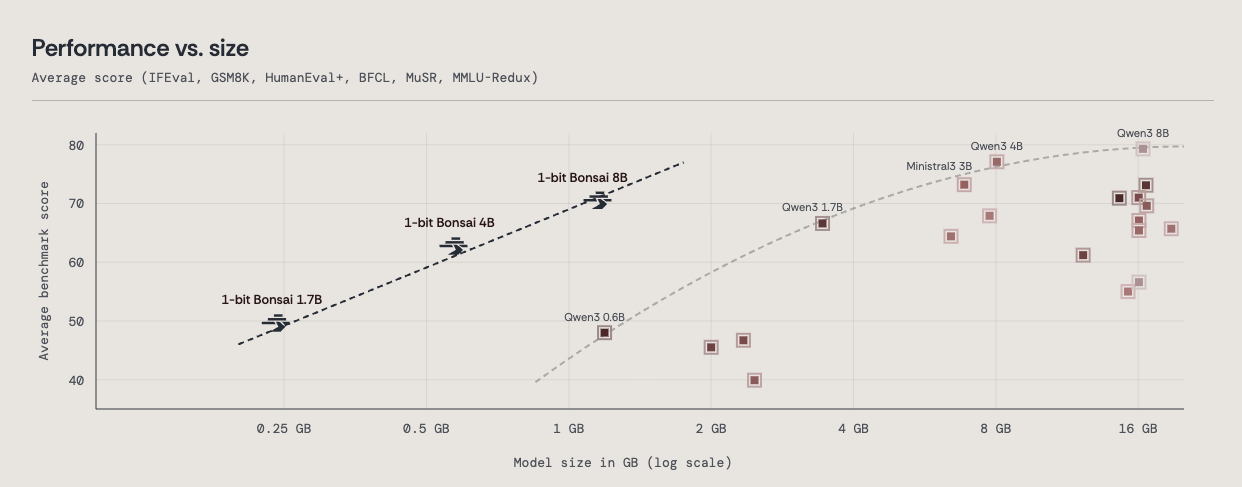
True 1-bit LLMs like PrismML’s Bonsai represent weights as single bits (0 or 1), enabling an 8B model to fit in just 1.15 GB. But this extreme compression has a cost: traditional adaptation methods like LoRA, fine-tuning, and quantization-aware training all require continuous weights or gradients that binary models lack. Until Bankai, there was no way to adapt a 1-bit model after training.
How XOR Patches Work
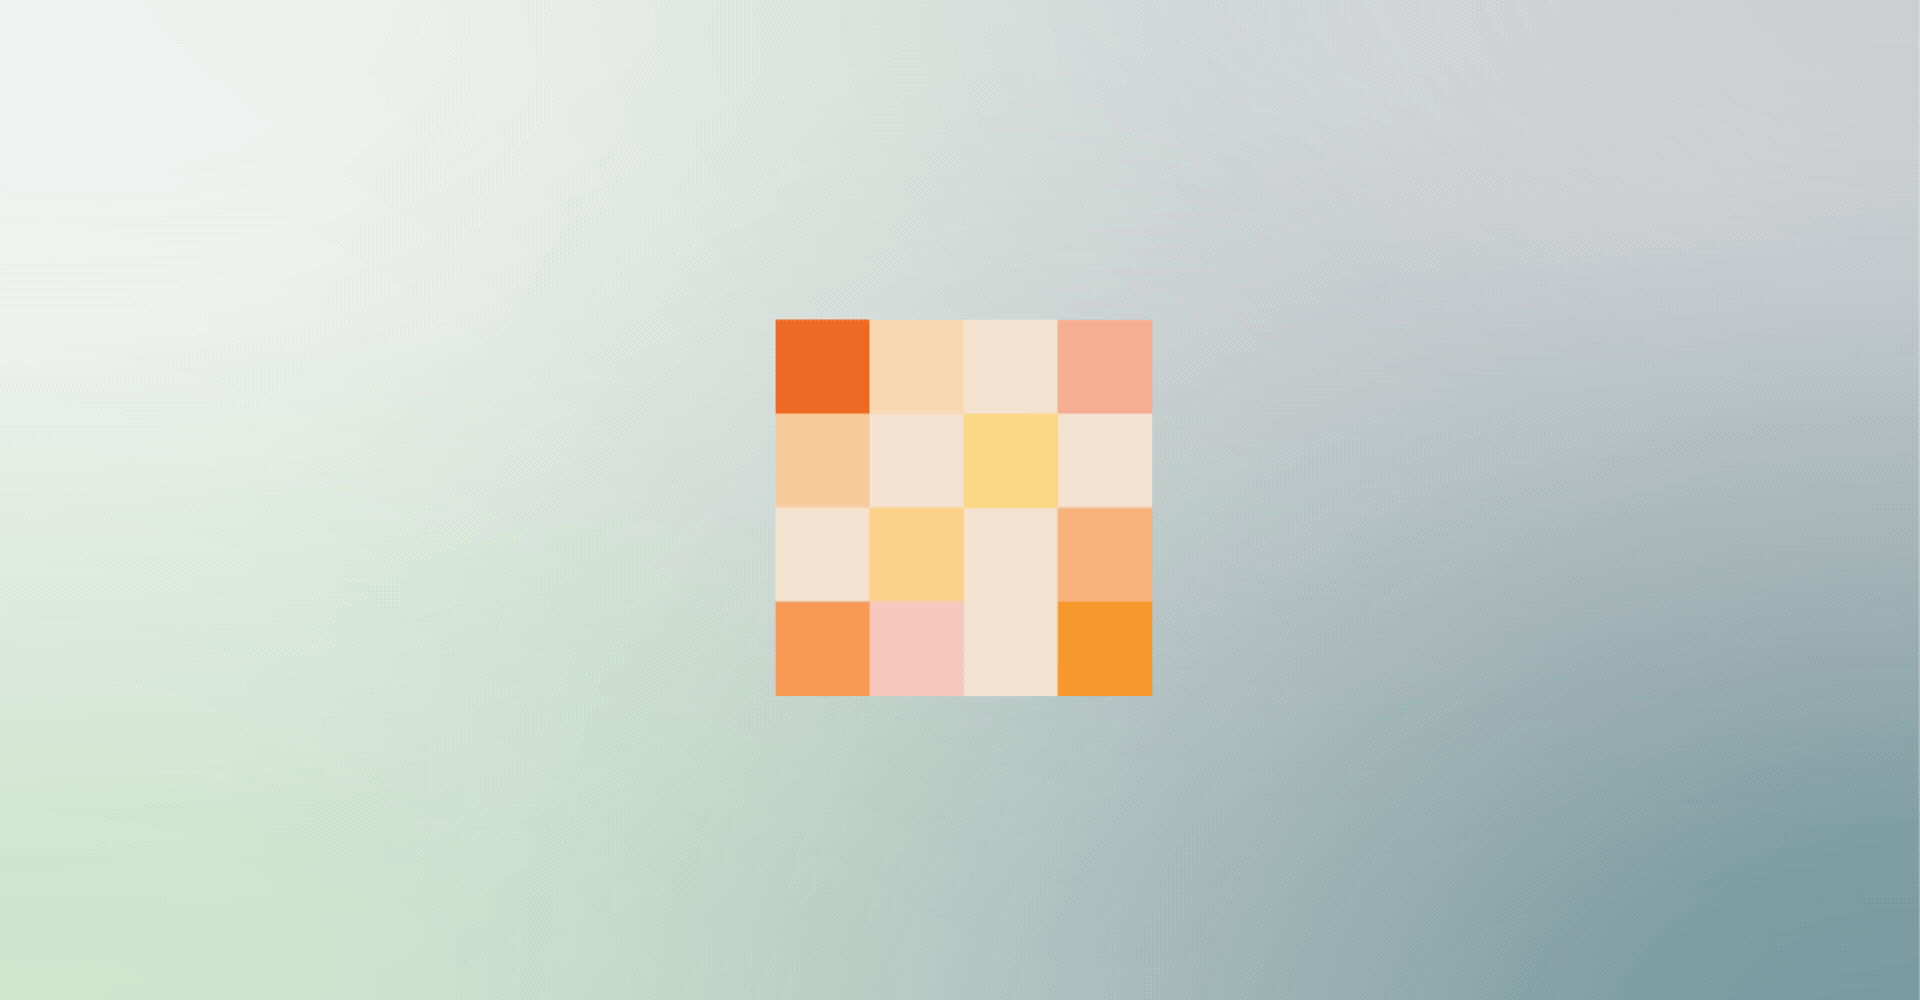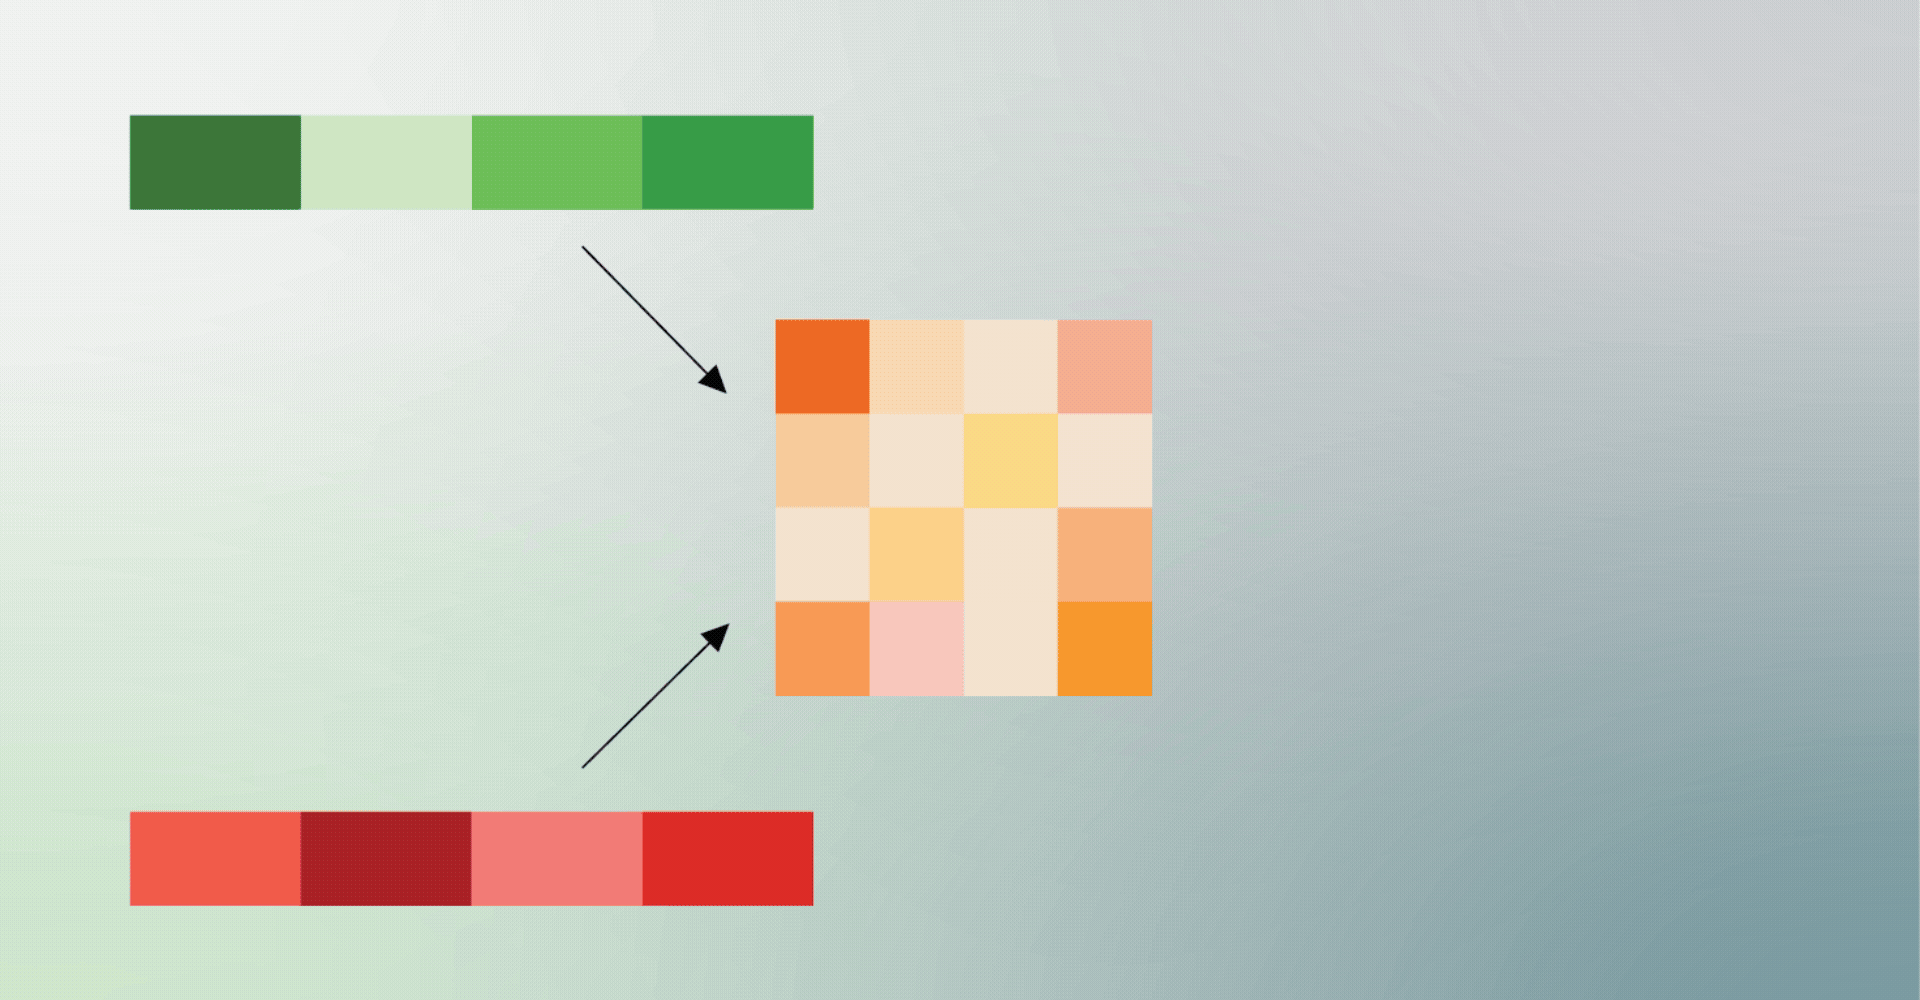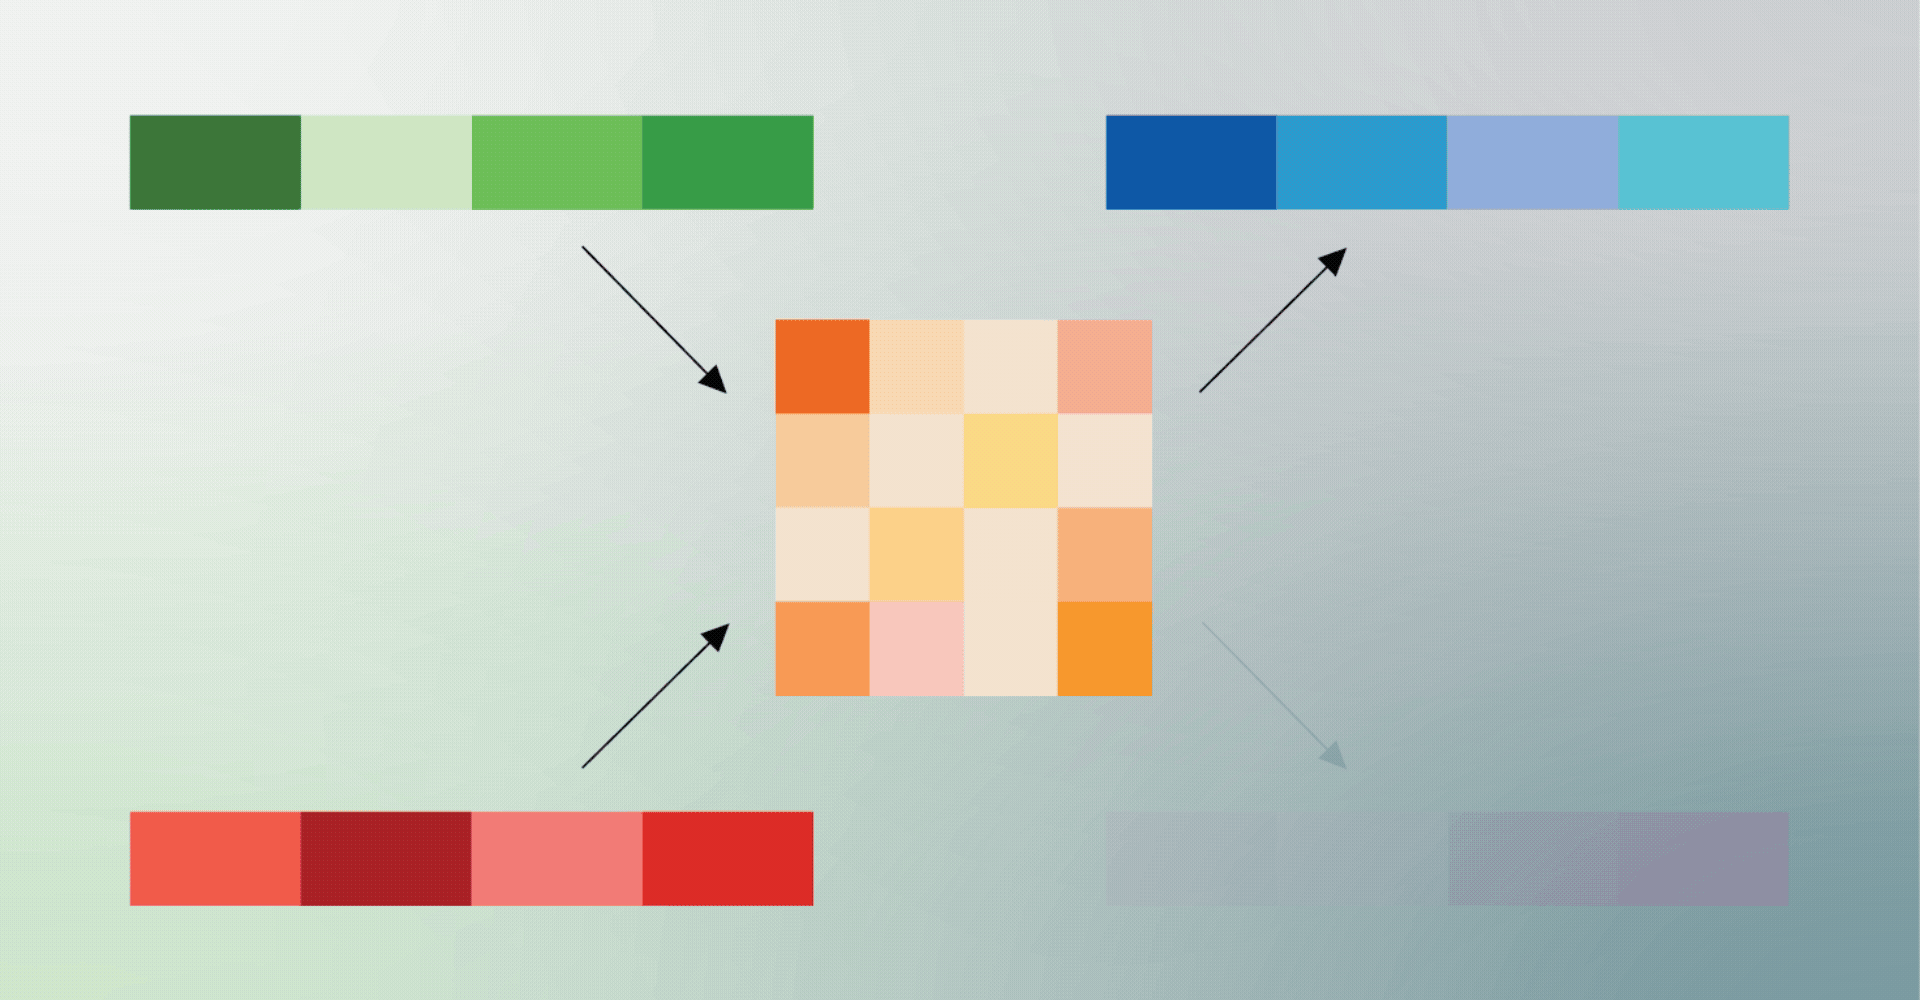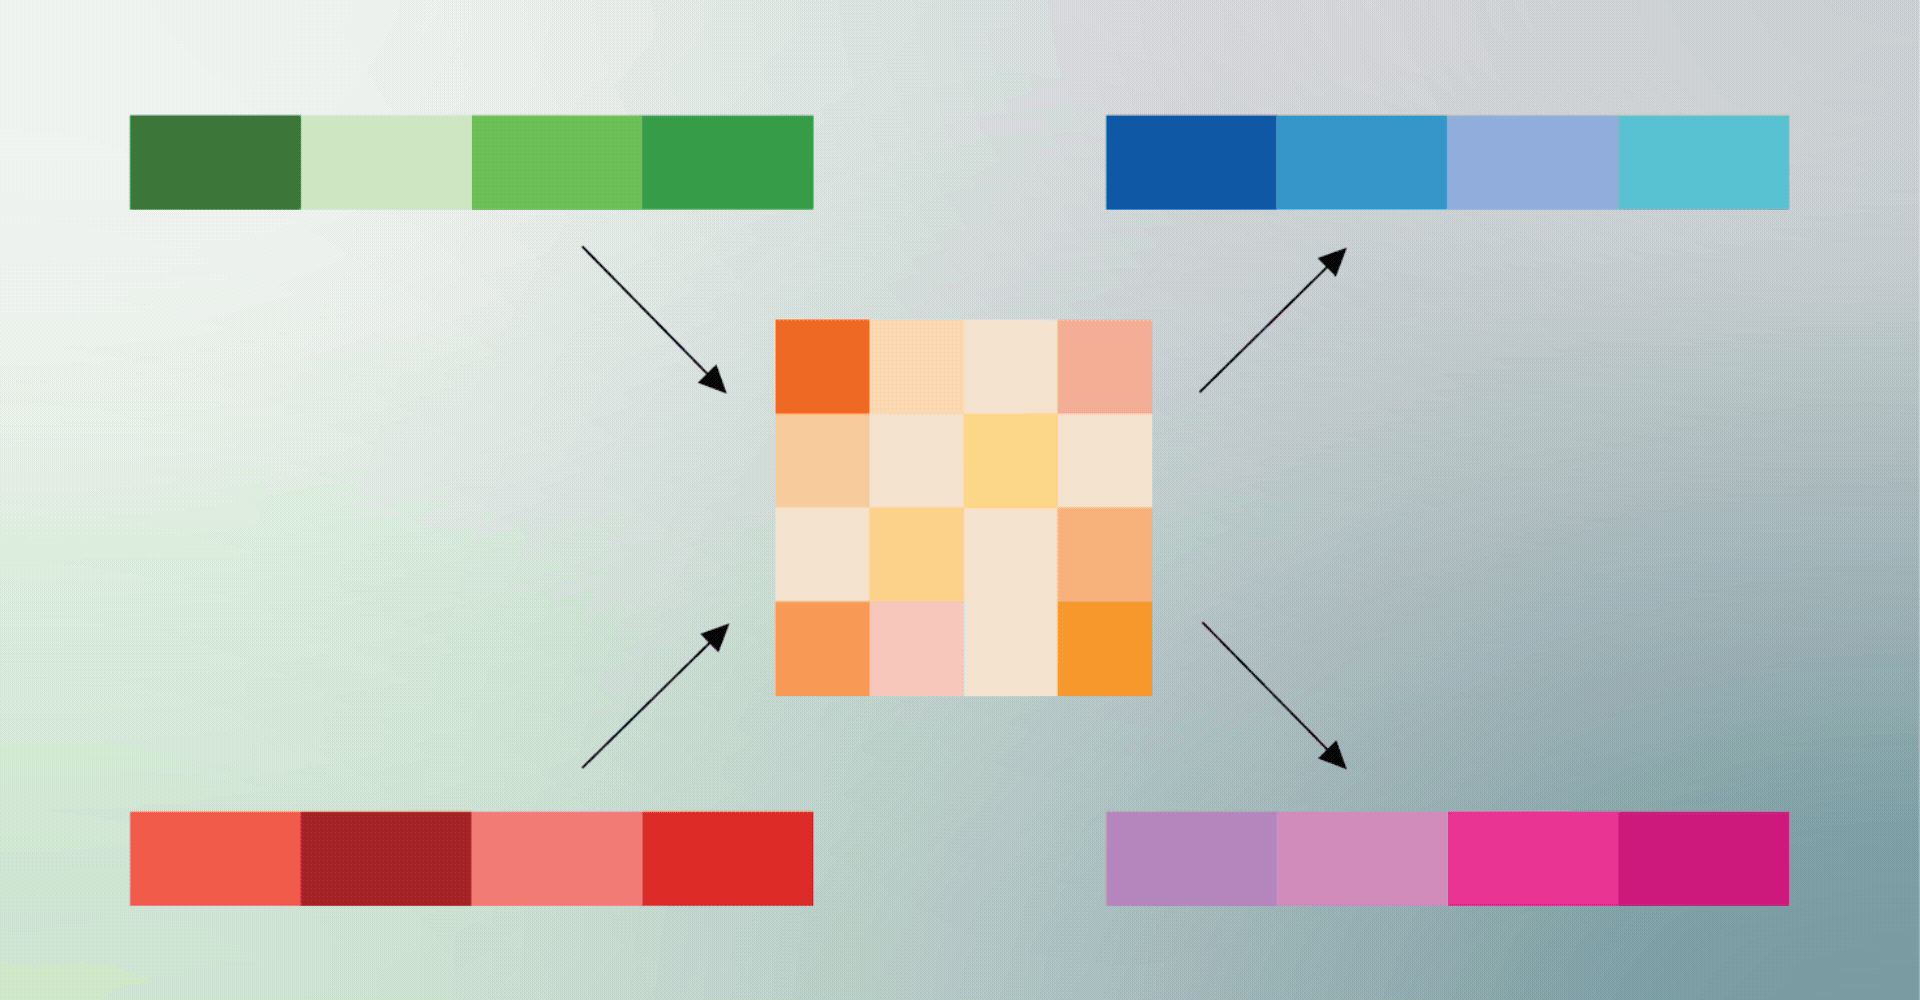
Bankai inverts the mechanism of bit-flip attacks — using constructive bit flips for targeted capability improvement instead of sabotage. Each patch is a sparse bitmask specifying which rows (entire neurons of 4,096 bits each) to flip across specific layers and projections. The operation is:
- Reversible — applying the same XOR patch twice restores the original weights
- Compact — a typical patch contains 72-93 flips, stored in 864 bytes to 1.1 KB
- Zero overhead — XOR is a single CPU instruction; no additional inference cost
- Hot-swappable — microsecond switching between domain-specialized configurations
Results
Validated on Bonsai 8B (the only production-grade true 1-bit LLM), Bankai demonstrated:
- Scale-guided targeting achieves 3.88× more behavioral impact than random flips
- A 72-flip arithmetic patch fixes several arithmetic failures while preserving all control probes
- A generalized patch trained on 60 diverse probes fixes 4 of 17 held-out problems (23.5%) with zero breakage on the 13 already solved
- No GSM8K degradation — general math reasoning remains intact with patches applied
- 500K random bit flips (0.009% of MLP weights) cause less than 0.08 perplexity change, revealing massive weight redundancy in 1-bit models
What This Means
Bankai opens a new paradigm for 1-bit model customization. Instead of retraining massive models, developers can create and distribute kilobyte-scale patches for specific capabilities — arithmetic, domain knowledge, safety alignment — and swap them at runtime. As 1-bit models like Bonsai mature, Bankai provides the missing piece: post-deployment adaptation without touching training infrastructure.
This post was drafted with AI assistance and reviewed by RITS staff.


 沪公网安备31011502017015号